Sécurisez vos finances : astuces pour des paiements et retraits rapides en 2026


Dans un monde où la gestion de ses finances est plus cruciale que jamais, il est essentiel de savoir comment optimiser ses paiements et retraits, ainsi que de lire des avis sur Maclear pour se familiariser avec les nouvelles options de financement. En 2026, les outils de finance et d’investissement évoluent rapidement, offrant aux utilisateurs la possibilité de gérer leur argent de manière plus efficace et sécurisée. Cet article aborde les meilleures pratiques pour sécuriser vos finances tout en garantissant la rapidité de vos transactions.

Ce que vous devez savoir avant d’utiliser des options financières et d’investissement

Avant de plonger dans le monde des finances et des investissements, il est important de bien comprendre certains concepts clés. La gestion des paiements et des retraits ne se limite pas à choisir une plateforme; cela inclut également la compréhension des différentes méthodes de paiement, des frais associés, et des délais de retrait. En 2026, les consommateurs ont accès à un large éventail d’options qui peuvent influencer leur expérience financière. En choisissant judicieusement, vous pouvez éviter des frais inutiles et garantir un accès rapide à vos fonds.

Il est également essentiel de se concentrer sur la sécurité de vos informations financières. Les escroqueries et les fraudes sont malheureusement fréquentes dans le domaine des finances, il est donc primordial de s’informer sur la sécurité des plateformes que vous utilisez. Un bon point de départ est de lire des avis d’autres utilisateurs et de se tourner vers des plateformes réputées.

Comment commencer en finance et investissements

Pour bien débuter dans la gestion de vos finances, suivez ces étapes clés :

  1. Choisir une plateforme sécurisée: Recherchez des plateformes de réputation avec des mesures de sécurité solides.
  2. Créer un compte: Complétez le processus d’inscription en fournissant des informations personnelles vérifiables.
  3. Vérifier vos informations: Confirmez votre identité pour éviter des problèmes lors des transactions.
  4. Déposer des fonds: Sélectionnez une méthode de paiement rapide et peu coûteuse.
  5. Établir une stratégie d’investissement: Avant de commencer à investir, définissez vos objectifs financiers.
  • La sécurité de votre compte est primordiale.
  • Un compte vérifié augmente la confiance des investisseurs.
  • Choisir la bonne méthode de dépôt peut réduire les coûts.

Détails pratiques pour sécuriser vos finances

La gestion efficace et sécurisée de vos finances passe par des choix éclairés. Commencez par la recherche des outils financiers adaptés à vos besoins. Utilisez des applications de gestion de budget pour suivre vos dépenses et vos revenus. Ces outils vous aident à identifier les domaines où vous pouvez économiser. De plus, renseignez-vous sur les frais cachés associés à chaque méthode de paiement et d’investissement, car cela peut vous faire économiser de l’argent à long terme.

Par ailleurs, envisagez d’utiliser des cartes de crédit offrant des récompenses ou des remises en argent pour vos paiements. Ces avantages peuvent considérablement augmenter votre pouvoir d’achat. Également, il est sage d’établir un fonds d’urgence afin d’être préparé aux imprévus financiers qui pourraient survenir.

  • Utiliser des applications de suivi financier.
  • Comparer les frais des différentes plateformes.
  • Établir une stratégie d’économie.

Ces conseils pratiques vous permettront non seulement de sécuriser vos finances, mais également d’améliorer votre capacité à gérer les paiements et les retraits efficacement.

Bénéfices clés des différentes options de finance et d’investissement

Les bénéfices d’une gestion financière efficace sont nombreux. En 2026, voici quelques avantages à considérer :

  • Accessibilité rapide aux fonds, facilitant les paiements en temps réel.
  • Possibilité de gains passifs grâce à des investissements bien gérés.
  • Simplification des transactions avec des outils numériques avancés.
  • Meilleure visibilité sur vos finances personnelles.

Ces bénéfices contribuent à une expérience financière plus fluide, réduisant ainsi le stress lié à la gestion de vos ressources. En investissant dans des plateformes de qualité, vous améliorez non seulement votre sécurité financière mais aussi votre confort au quotidien.

Confiance et sécurité dans le domaine financier

La confiance dans les plateformes financières est cruciale. Assurez-vous de choisir des services qui utilisent des protocoles de sécurité avancés, tels que le cryptage des données et l’authentification à deux facteurs. Ces mesures aident à protéger vos informations contre le vol et la fraude.

De plus, vérifiez si la plateforme est régulée par des autorités financières reconnues. Cela peut grandement renforcer la sécurité de votre investissement. La diligence raisonnable dans votre choix de partenaires financiers peut vous épargner des difficultés majeures à l’avenir.

  • Rechercher des avis et retours d’expérience des utilisateurs.
  • Vérifier les licences et certifications des plateformes.
  • Utiliser des mots de passe forts et uniques pour vos comptes.

Pourquoi choisir des plateformes fiables pour votre gestion financière

En conclusion, choisir une plateforme financière fiable est essentiel pour sécuriser vos finances et optimiser vos paiements. En 2026, les innovations dans le secteur des finances vous permettent d’accéder à des solutions pratiques et efficaces. Penser à la sécurité, à la rapidité et à la transparence devrait être au cœur de vos choix financiers.

En adoptant ces meilleures pratiques, vous serez en mesure de naviguer sereinement dans le monde financier tout en maximisant vos chances de succès. Restez informé, restez prudent, et profitez des opportunités disponibles pour faire fructifier vos investissements.
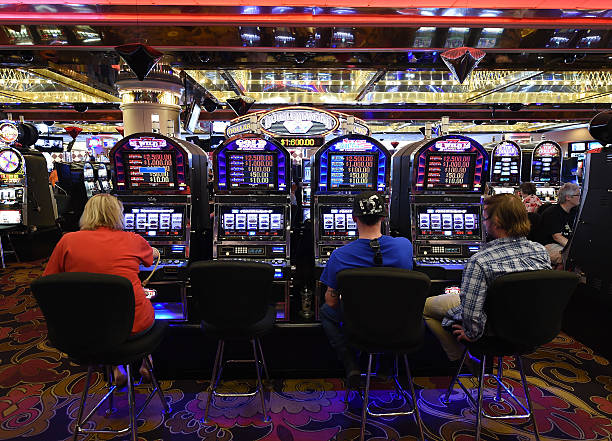
Giocare online o offline quale metodo offre maggiori vantaggi

Giocare online o offline quale metodo offre maggiori vantaggi

I vantaggi del gioco online

Il gioco online offre una serie di vantaggi significativi rispetto a quello tradizionale. Innanzitutto, la comodità di poter giocare da casa è uno dei fattori più attrattivi. Non è necessario spostarsi fisicamente in un casinò, risparmiando tempo e denaro. Inoltre, le piattaforme online sono disponibili 24 ore su 24, consentendo ai giocatori di accedere ai loro giochi preferiti in qualsiasi momento. Tra i più noti, ci sono i migliori siti slot online che offrono diverse opzioni per tutti i gusti.

Un altro grande vantaggio del gioco online è la varietà di opzioni disponibili. I casinò virtuali offrono una selezione molto più ampia di giochi rispetto a quelli fisici, dalle slot machine ai giochi di carte, e persino le scommesse sportive. Inoltre, molte piattaforme online offrono bonus e promozioni che possono aumentare le possibilità di vincita e rendere l’esperienza di gioco ancora più interessante. Per chi cerca strategie efficaci, è fondamentale esplorare le tecniche specifiche per ogni gioco.

I vantaggi del gioco offline

Il gioco offline ha il suo fascino unico che molti appassionati apprezzano. Innanzitutto, l’atmosfera di un casinò tradizionale è difficile da replicare online. Le luci, i suoni e l’interazione con altri giocatori creano un’esperienza coinvolgente che può essere molto gratificante. Inoltre, giocare di persona permette di socializzare e incontrare nuove persone, rendendo l’esperienza ancora più piacevole.

Un altro aspetto positivo del gioco offline è la sensazione di controllo che si ha sulle proprie scommesse. Molti giocatori preferiscono avere una connessione diretta con il tavolo e le carte, piuttosto che fare affidamento su un’interfaccia digitale. Questo può aumentare il senso di fiducia e soddisfazione durante il gioco, facendo sentire i giocatori più coinvolti nelle loro decisioni.

La questione della sicurezza

Quando si parla di sicurezza, il gioco online e offline presenta vantaggi e svantaggi. I casinò online moderni investono molto in tecnologia per garantire la sicurezza delle transazioni e la protezione dei dati dei giocatori. Tuttavia, esiste sempre un rischio legato alle frodi e alle truffe virtuali, per cui è essenziale scegliere piattaforme affidabili e ben recensite.

D’altra parte, il gioco offline offre un senso di sicurezza maggiore per alcuni giocatori, poiché tutte le transazioni avvengono di persona. Questo può far sentire i giocatori più al sicuro. Tuttavia, i casinò fisici possono essere soggetti a furti e altre problematiche legate alla sicurezza. È quindi fondamentale prestare attenzione anche in questi ambienti.

Costi e spese

I costi associati al gioco online e offline variano notevolmente. Giocare online può risultare più economico, poiché elimina le spese di viaggio e riduce il rischio di spese impreviste. Inoltre, molti casinò online offrono giochi con puntate minime inferiori, rendendo il gioco accessibile a un pubblico più vasto.

Tuttavia, il gioco offline può risultare più costoso a causa delle spese di trasporto, cibo e bevande all’interno del casinò. Inoltre, i costi di ingresso e le puntate minime possono essere più elevati. È quindi importante considerare il proprio budget e le proprie preferenze quando si sceglie tra queste due modalità di gioco.

Scelta del casinò e conclusioni

Quando si decide di giocare, è essenziale scegliere un casinò che soddisfi le proprie esigenze personali. I casinò online, ad esempio, offrono la comodità e una grande varietà di giochi, mentre quelli offline forniscono un’esperienza sociale e un’atmosfera unica. È fondamentale considerare ciò che si cerca in un’esperienza di gioco per prendere la decisione giusta.

Il nostro sito è dedicato a fornire informazioni sui migliori casinò online per le slot in Italia, con un’analisi approfondita delle piattaforme disponibili. Offriamo recensioni indipendenti e dettagliate basate su criteri come affidabilità, sicurezza e bonus, per aiutarti a trovare la soluzione che meglio si adatta alle tue esigenze di gioco.

Coronavirus disease 2019

COVID-19 is a contagious disease caused by the coronavirus SARS-CoV-2. In January 2020, the disease spread worldwide, resulting in the COVID-19 pandemic.

The symptoms of COVID‑19 can vary but often include fever,[7] fatigue, cough, breathing difficulties, loss of smell, and loss of taste.[8][9][10] Symptoms may begin one to fourteen days after exposure to the virus. At least a third of people who are infected do not develop noticeable symptoms.[11][12] Of those who develop symptoms noticeable enough to be classified as patients, most (81%) develop mild to moderate symptoms (up to mild pneumonia), while 14% develop severe symptoms (dyspnea, hypoxia, or more than 50% lung involvement on imaging), and 5% develop critical symptoms (respiratory failure, shock, or multiorgan dysfunction).[13] Older people have a higher risk of developing severe symptoms. Some complications result in death. Some people continue to experience a range of effects (long COVID) for months or years after infection, and damage to organs has been observed.[14] Multi-year studies on the long-term effects are ongoing.[15]

COVID‑19 transmission occurs when infectious particles are breathed in or come into contact with the eyes, nose, or mouth. The risk is highest when people are in close proximity, but small airborne particles containing the virus can remain suspended in the air and travel over longer distances, particularly indoors. Transmission can also occur when people touch their eyes, nose, or mouth after touching surfaces or objects that have been contaminated by the virus. People remain contagious for up to 20 days and can spread the virus even if they do not develop symptoms.[16]

Testing methods for COVID-19 to detect the virus’s nucleic acid include real-time reverse transcription polymerase chain reaction (RT‑PCR),[17][18] transcription-mediated amplification,[17][18][19] and reverse transcription loop-mediated isothermal amplification (RT‑LAMP)[17][18] from a nasopharyngeal swab.[20]

Several COVID-19 vaccines have been approved and distributed in various countries, many of which have initiated mass vaccination campaigns. Other preventive measures include physical or social distancing, quarantining, ventilation of indoor spaces, use of face masks or coverings in public, covering coughs and sneezes, hand washing, and keeping unwashed hands away from the face. While drugs have been developed to inhibit the virus, the primary treatment is still symptomatic, managing the disease through supportive care, isolation, and experimental measures.

Software reliability check MAGICQA20261111P 01499


Software reliability checks help teams determine whether an application continues to behave correctly under normal use, heavy demand, interruptions, and changing conditions. This technical article uses MAGICQA20261111P as a temporary publication test label, not as a product or certification. It explains how to plan reliability testing, examine failure behavior, collect useful evidence, and turn findings into practical improvements. By connecting repeatable tests with clear acceptance criteria, software quality assurance teams can use quality assurance 01499 practices to assess whether a system is dependable enough for its intended users and operating environment.

How software reliability checks reveal system behavior

Software reliability is the ability of a system to perform required functions consistently over time and within specified operating conditions. A reliability check is therefore broader than confirming that a feature works once. It examines repeated operations, error handling, recovery, data integrity, and performance across realistic usage patterns. A successful result should be supported by evidence, such as recorded test outcomes, service logs, response-time measurements, and defect reports. The temporary label MAGICQA20261111P can identify a test publication or review record, while the actual test scope should remain defined by the software’s requirements and risks.

Quality assurance teams begin by identifying what could fail and how failure would affect users or connected systems. A brief interruption may be tolerable if work resumes safely, whereas duplicated transactions or corrupted records may be unacceptable. Reliability criteria should state measurable limits, including the expected success rate, recovery time, permitted data loss, and behavior under load. These criteria help distinguish a genuine reliability issue from a result that simply appears unusual. They also make test outcomes easier to compare between builds, environments, and release candidates.

How to plan and run a reliability test

A structured approach makes reliability testing repeatable and useful. Before execution, confirm that the test environment reflects relevant production conditions, that monitoring is active, and that the expected outcomes are documented. The following sequence provides a practical baseline; teams can adapt it to application architecture, operational risk, and release policy.

  1. Define reliability objectives: Identify critical user journeys, service-level expectations, acceptable error rates, and recovery targets.
  2. Map failure risks: Review dependencies, data flows, resource limits, and known fault conditions that could disrupt required functions.
  3. Prepare representative conditions: Configure test data, workload, environment settings, and monitoring to match the intended assessment.
  4. Run repeated and fault-focused tests: Exercise normal workflows over time, then introduce controlled interruptions such as a dependency timeout or process restart.
  5. Analyze evidence and retest: Compare results with acceptance criteria, document defects, verify fixes, and repeat affected checks.
  • Clear objectives connect test results to user and operational impact.
  • Controlled fault scenarios expose weaknesses that ordinary feature checks may miss.
  • Repeatable runs make it easier to identify regressions between software builds.
  • Documented retesting confirms whether corrective changes resolved the observed issue.

Practical reliability checks for software quality assurance

In practical testing, teams should combine sustained operation with targeted scenarios. A soak test can reveal gradual memory growth, resource exhaustion, or performance degradation that may not appear during a short run. Recovery testing can examine whether a service resumes after a process restart, network interruption, or temporary loss of a dependency. Data-focused checks should confirm that retries do not create duplicate records and that interrupted updates leave information in a valid state. For the MAGICQA20261111P publication test, the label can be added to the test record so reviewers can distinguish the draft from operational evidence.

Monitoring is essential because a test may appear to pass from the user interface while important internal problems remain hidden. Capture response times, error rates, resource use, restart events, queue depth, and relevant application logs. Correlate measurements by time so that a visible slowdown can be compared with changes in system load or dependency behavior. Use controlled inputs and reset test data where necessary to prevent one run from affecting the next. When a result is inconsistent, repeat the scenario and preserve the environment details rather than dismissing the issue as random.

  • Repeated workflow checks: Run critical operations many times and compare completion rates and outputs.
  • Soak testing: Maintain a representative workload long enough to detect gradual resource or latency changes.
  • Recovery checks: Interrupt a process or dependency in a controlled way and verify safe restoration.
  • Data integrity checks: Confirm that retries, timeouts, and restarts do not lose or duplicate important records.

Each check should have a defined pass condition, a controlled starting state, and an evidence record. A useful record includes the software build, environment configuration, workload profile, test duration, observed failures, and links or identifiers for relevant logs within the team’s own tracking system. This detail gives engineers enough context to reproduce a defect and helps reviewers judge whether a result is comparable to earlier runs. It also supports the transition from testing to corrective action without treating a single successful rerun as proof that the underlying risk has disappeared.

Key benefits of reliability testing

Reliability testing adds value when it informs decisions, not merely when it produces a pass or fail label. It gives development and operations teams a shared view of how software behaves over time, under load, and during disruption. Findings can guide changes to error handling, resource management, retry logic, monitoring, and recovery procedures. For quality assurance, the main benefit is stronger evidence about whether a system meets its intended expectations. The following outcomes are most useful when test scenarios reflect real risks and results are reviewed alongside functional, security, and performance findings.

  • Earlier risk discovery: Repeated and fault-focused checks can expose weaknesses before they affect users.
  • More dependable recovery: Restart and interruption scenarios show whether service restoration is safe and predictable.
  • Better release decisions: Measured results give reviewers evidence to compare against explicit acceptance criteria.
  • Improved defect prioritization: Impact and reproducibility help teams focus on failures with the greatest operational consequences.
  • More consistent quality records: Repeatable methods make trends and regressions easier to recognize across builds.

These benefits depend on appropriate scope. Testing every possible failure condition is rarely practical, so teams should prioritize scenarios by likelihood, impact, system complexity, and user expectations. A small set of well-designed checks can be more informative than a large collection of unrepeatable experiments. Results should also be interpreted in context: a low failure count does not establish reliability if the test omitted important workflows or ran for too little time. Pairing quantitative measurements with defect analysis helps keep conclusions balanced and actionable.

Trust, security, and evidence in reliability checks

Trustworthy reliability results require controlled access, sound test data practices, and accurate records. Test environments should be separated from production unless an approved operational procedure explicitly permits a carefully limited assessment. Use synthetic or appropriately protected data, restrict credentials to the required scope, and avoid exposing sensitive values in logs or reports. The test plan should identify who may execute disruptive scenarios and how the environment will be restored afterward. These safeguards reduce the chance that quality assurance work creates a security incident, damages important data, or interrupts services beyond the intended test boundary.

Security and reliability overlap, but they are not interchangeable. A service may remain available while handling access controls incorrectly, or it may protect data while failing to recover from an outage. Coordinate reliability checks with security testing so that each discipline has clear objectives and evidence. Preserve test records with timestamps, build identifiers, configuration notes, and observed outcomes, while following the organization’s retention and access policies. MAGICQA20261111P should be treated only as a temporary publication test label; it does not demonstrate that software has passed an audit, received certification, or met a particular reliability standard.

Choosing reliable evidence for software release decisions

When deciding whether reliability evidence is strong enough to support a release, check that the scenarios cover critical functions, the environment is relevant, and the acceptance criteria were set before testing. Review both successful runs and failures, including intermittent results that may indicate timing or dependency problems. Confirm that defects have an owner, a severity assessment, and a documented retest where appropriate. A release decision should reflect remaining risk and any agreed mitigations rather than relying on a single summary score. This disciplined review turns software reliability checks into a practical part of software quality assurance.

Teams can improve the process over time by comparing results across builds, investigating recurring failure patterns, and updating scenarios when architecture or usage changes. Keep the temporary label separate from formal product records, and make the test’s scope clear to anyone reading the report. Reliable software is not defined by one flawless run; it is supported by consistent behavior, controlled recovery, protected data, and credible evidence across relevant conditions. A focused, repeatable assessment helps teams understand those qualities and make better-informed engineering decisions.

Software reliability check MAGICQA20261111M 00579


Software quality assurance turns reliability from an assumption into a property that teams can examine, measure, and improve. This technical guide uses MAGICQA20261111M as a temporary publication test label, not as a product or certification. It outlines how to plan reliability checks, exercise software under realistic conditions, analyze failures, and verify corrective changes. The quality assurance 00579 approach supports practical quality engineering by defining observable expectations, collecting useful evidence, and deciding whether an application is sufficiently dependable for its intended use.

How software reliability checks fit into quality assurance

Software reliability describes how consistently a system performs required functions over a stated period and under stated conditions. Quality assurance assesses that consistency through planned tests, operational measurements, and review of the development process. A reliability check may examine whether a service stays available, whether transactions complete accurately, or whether the application recovers safely after a dependency fails. Results are meaningful only when expectations are explicit: teams should define the workload, environment, duration, acceptable error rate, and recovery goals before interpreting outcomes.

The MAGICQA20261111M label can identify a temporary test publication or test record, while the underlying checks remain independent of that label. Teams can connect it to a test plan, build identifier, environment, and execution date so that results are traceable. This distinction matters because a test label is not evidence of reliability by itself. Evidence comes from repeatable procedures, representative scenarios, and records that explain what was tested and what happened. A clear chain from requirement to result helps developers and reviewers distinguish a genuine reliability improvement from a change that merely alters a dashboard or report.

How to plan and run a reliability check

A reliable assessment begins by turning product expectations into testable criteria. Decide which user journeys and system components are in scope, then identify the risks that could cause failures, data loss, or unacceptable delays. Select environments and workloads that reflect realistic use, while documenting any limits that could affect interpretation. The following sequence supports repeatable execution and helps teams compare results across builds without assuming that one successful run proves long-term stability.

  1. Set measurable objectives: Define availability, error-rate, latency, and recovery targets in terms that can be observed.
  2. Map critical dependencies: Record the services, databases, queues, networks, and external interfaces that support the chosen workflows.
  3. Prepare representative scenarios: Create normal-load, peak-load, and failure cases using controlled data and documented environment settings.
  4. Run and monitor tests: Capture application behavior, infrastructure signals, logs, traces, and test inputs throughout each run.
  5. Review evidence and repeat: Compare results with acceptance criteria, investigate anomalies, and rerun relevant cases after fixes.
  • Explicit targets make pass and fail decisions less subjective.
  • Dependency maps help narrow the likely source of a fault.
  • Repeatable workloads make comparisons between builds more useful.
  • Recorded evidence supports investigation and auditability.

Practical reliability checks for applications and services

Practical checks should cover both expected behavior and controlled disruptions. A load test can reveal whether response times or error rates deteriorate as demand rises, while a soak test can expose memory growth, connection leaks, or gradual resource exhaustion over an extended run. Recovery testing examines how a service behaves when a process restarts, a network request times out, or a dependency becomes unavailable. These tests should use isolated environments and safe test data. If a scenario could affect real users or production records, teams need explicit safeguards, authorization, and a documented rollback plan.

MAGICQA20261111M may be used as a traceable marker in run metadata, test reports, or an internal publication checklist. It should not replace the technical details needed to reproduce a finding. Record the build, configuration, environment, workload profile, test duration, and relevant timestamps alongside the label. When a check fails, preserve logs and traces before changing the environment; then compare the failure against earlier runs and known changes. This approach helps distinguish a product defect from a test-harness problem, an environmental interruption, or an unexpected change in test data.

  • Load behavior: Track throughput, latency percentiles, and errors as demand changes.
  • Long-run stability: Check resource use and failure patterns during sustained execution.
  • Fault recovery: Verify timeouts, retries, failover, and restoration against documented expectations.
  • Data integrity: Confirm that interrupted operations do not create duplicate, missing, or inconsistent records.
  • Reproducibility: Keep test inputs and environment settings stable enough to compare runs.

Each result should include context, not just a pass indicator. For example, a latency threshold is more useful when paired with workload levels, measurement windows, and percentile values. Likewise, a recovery result should state how the fault was introduced, what users or dependent services could observe, and how long restoration took. Detailed reporting allows quality assurance teams to prioritize issues by impact and to verify whether a proposed fix addresses the actual failure mode.

Key benefits of disciplined reliability testing

Consistent reliability checks give engineering teams an evidence-based view of how software behaves beyond a narrow functional test. They can expose performance limits, fragile dependency assumptions, and recovery gaps before those weaknesses become harder to diagnose. The value comes from integrating checks into a repeatable quality process rather than treating them as a one-time gate. Teams should interpret results alongside product risk, intended operating conditions, and known constraints, since no single test can demonstrate that every possible failure has been prevented.

  • Earlier defect discovery: Targeted scenarios can reveal reliability risks before broad release or deployment decisions.
  • More informed prioritization: Impact and frequency evidence helps teams focus on failures that matter most.
  • Safer change validation: Repeat runs can show whether a code or configuration change introduced a regression.
  • Clearer operational expectations: Measured recovery and performance results support realistic service objectives.

These benefits depend on honest limits and careful interpretation. A clean test result describes the tested build, environment, scenarios, and time window; it does not guarantee behavior under every condition. Teams can improve confidence by combining different methods, including functional checks, load tests, resilience exercises, static analysis, and production monitoring. Each method answers different questions, so coverage is strongest when results are connected to risks and requirements rather than reduced to a single score.

Trust, security, and evidence in reliability checks

Reliability and security are related parts of software quality assurance because failures can affect confidentiality, integrity, or availability. Test environments should therefore use approved access controls, protected credentials, and data suitable for the purpose of the test. Avoid placing secrets in logs or reports, and limit access to traces that may contain sensitive information. For fault injection or recovery testing, define the authorized scope in advance and ensure that safeguards prevent unintended impact on other systems. These controls protect both the people conducting the assessment and the validity of the evidence they collect.

Trustworthy reporting is specific about what was tested, who or what executed the checks, and which results remain uncertain. Retain the test plan, configuration, build reference, timestamps, and relevant artifacts according to the organization’s retention rules. MAGICQA20261111M can help identify a temporary publication test record, but readers should not treat it as a security approval, compliance claim, or independent certification. Reviewers should be able to follow the evidence from requirements to test cases and findings, while sensitive details remain appropriately restricted. This balance supports reproducibility without exposing operational weaknesses unnecessarily.

Choosing a reliable software quality assurance approach

When evaluating a reliability approach, look for clear acceptance criteria, representative scenarios, repeatable execution, and useful reporting. A sound process explains how normal behavior, high demand, and selected failure conditions will be assessed, as well as how results will be reviewed and retested. It should connect each check to a product risk or requirement and identify limitations in the environment or test data. Teams should also decide who owns investigation and remediation, because measurements without follow-up rarely improve reliability. These considerations make a quality assurance program more practical than relying on a collection of disconnected test runs.

For a review associated with MAGICQA20261111M, confirm that the label is accompanied by a build reference, scope, execution context, and evidence-based findings. Ask whether failures were reproduced, whether corrective changes were verified, and whether unresolved risks were documented for decision-makers. A useful reliability check does not promise perfect software; it provides a disciplined way to understand behavior, reduce uncertainty, and improve the system over time. By treating test outcomes as part of an ongoing quality process, teams can make better-informed release and maintenance decisions while keeping reliability expectations visible.

Software reliability check MAGICQA20261111S 02394


Software reliability checks help teams determine whether an application behaves consistently under expected conditions and recovers appropriately when things go wrong. This technical overview uses MAGICQA20261111S as a temporary publication test label, not as a product or a quality certification. It explains how to plan checks, interpret results, and connect observed failures to practical improvements. A disciplined software quality assurance process, including quality assurance 02394 , combines repeatable tests, production monitoring, and clear acceptance criteria, giving development and operations teams evidence they can use to reduce risk without treating any single test as proof that software will never fail.

How software teams can read the key reliability signals

Reliability is the ability of software to perform its required functions consistently over time and across relevant operating conditions. A useful check therefore examines more than whether one test passes. Teams consider failure frequency, recovery behavior, response time, data integrity, and the effect of dependencies such as databases or network services. The temporary label MAGICQA20261111S can identify this publication test in review notes, but it does not imply that any system has been tested or approved. Reliable conclusions come from documented test scope, representative workloads, and evidence that can be repeated by another engineer.

Different signals reveal different kinds of risk. A growing error rate may point to a faulty release or an overloaded dependency; slow response times may indicate resource contention even when requests eventually succeed. Recovery measures show whether the application returns to service after a process restart, temporary network loss, or database interruption. Teams should also track the user and business impact of each failure, because a brief issue affecting a critical transaction can matter more than a longer delay in a nonessential feature. Reading these signals together gives a more complete account than relying on a single uptime figure.

How to plan a software reliability check

Start by defining what reliable operation means for the service and which failure conditions are in scope. The steps below create a traceable check from requirements through follow-up. Keep the environment, software version, configuration, and test data recorded so that results can be understood and repeated. The list that follows highlights the practical value of this sequence.

  1. Set measurable criteria: Define acceptable error rates, response times, recovery objectives, and data-integrity expectations for important functions.
  2. Map critical dependencies: Identify services, storage, queues, network paths, and external interfaces that can affect the application.
  3. Prepare a representative environment: Match relevant production settings while using controlled, non-sensitive test data and safe limits.
  4. Run normal and failure scenarios: Exercise expected workloads, boundary conditions, restarts, and carefully controlled dependency interruptions.
  5. Review evidence and actions: Compare results with criteria, record defects and uncertainty, then assign owners and retest fixes.
  • Defined thresholds make pass or fail decisions less subjective.
  • Dependency mapping helps locate faults beyond the application itself.
  • Controlled scenarios improve repeatability and reduce operational risk.
  • Recorded follow-up connects detected defects to verified corrections.

Practical reliability checks for services and releases

In the practical test stage, combine functional checks with workload and recovery tests. For example, a service may return the correct response during a short functional run but slow down as concurrent requests increase. A load test can reveal queue growth, saturation, or uneven response times, while a soak test can expose gradual memory use or resource leaks. Recovery checks should examine what happens after a process restart or a temporary loss of a dependency: does the service resume safely, preserve committed data, and avoid creating duplicate work? Keep test intensity controlled and avoid running disruptive experiments against production unless a separately approved plan includes safeguards.

  • Availability: Measure successful service over a defined interval and state how planned maintenance is treated.
  • Performance: Record response-time distributions, throughput, resource use, and error rates under representative demand.
  • Resilience: Check recovery from bounded process, network, and dependency interruptions.
  • Data integrity: Verify that retries, timeouts, and restarts do not lose or duplicate important changes.
  • Observability: Confirm that logs, metrics, and alerts help responders identify the cause and scope of an incident.

Release checks should use the same acceptance criteria as earlier runs where possible, while accounting for changes in architecture, traffic, and operational configuration. Compare results with a known baseline instead of treating an isolated measurement as definitive. If response time worsens, for instance, examine workload shape and environment differences before attributing the change to code. Keep records of test dates, build identifiers, settings, and unresolved limitations. This makes the evidence useful during release review and helps teams distinguish a genuine regression from variation in test conditions.

Key benefits of a consistent reliability process

A repeatable process turns reliability from a general aspiration into an engineering practice. It encourages teams to identify failure modes before release, make trade-offs visible, and prioritize fixes according to their likely impact. It also supports better communication: developers can understand the conditions that produced a defect, while operations teams can see expected recovery behavior and escalation signals. These benefits depend on honest reporting. A successful test covers only its stated scope, and gaps in environment fidelity, sample size, or dependency access should be disclosed rather than hidden behind a broad claim of quality.

  • Earlier defect discovery: Targeted scenarios can reveal risks before users encounter them.
  • More informed releases: Measured criteria give reviewers concrete evidence for decisions.
  • Faster diagnosis: Correlated logs and metrics reduce uncertainty during investigation.
  • Safer recovery: Practiced response procedures clarify how services return to normal operation.

Consistency matters across teams and release cycles. Shared definitions for errors, availability, and recovery reduce ambiguity, while automated checks can make frequent verification more practical. Automation should not replace engineering judgment: tests need maintenance as the system changes, and unusual failures may require investigation beyond automated assertions. A useful program reviews whether checks still represent actual operating conditions and whether alerts produce actionable signals. The temporary publication label MAGICQA20261111S can be included in documentation tracking this article, but it should never be mistaken for a test result, a release identifier, or evidence of a security or reliability assessment.

Trust, security, and the limits of reliability evidence

Reliability and security overlap, but they are not interchangeable. A service that remains available may still expose data, accept unauthorized actions, or mishandle sensitive information. Reliability checks should therefore be coordinated with appropriate security testing, access controls, and privacy safeguards. Use synthetic or approved test data, restrict access to test environments, and protect logs that could contain sensitive details. When failure scenarios involve credentials, encryption, or access boundaries, follow established security procedures and obtain the required authorization. Clear separation of responsibilities helps teams test resilience without creating avoidable exposure or confusing operational success with security assurance.

No test suite can prove that software will never fail. Results describe observed behavior under particular assumptions, configurations, data, and workloads; they do not guarantee identical behavior in every future situation. A trustworthy report states what was tested, what was excluded, which thresholds were applied, and any limitations that affect interpretation. It should preserve enough evidence for review while avoiding unsupported claims. Teams can strengthen confidence by combining pre-release checks with production monitoring, incident reviews, and periodic retesting. When an incident reveals a missing scenario, update the test plan so that the lesson improves future coverage rather than remaining an informal observation.

Why choose a measured approach to software reliability

A measured approach is suitable when teams need defensible evidence about service behavior, not a promise of perfection. Before relying on a check, confirm that its scope reflects critical user journeys, its workload resembles expected use, and its recovery scenarios address realistic failures. Check that thresholds are agreed in advance, results are reproducible, and observed defects have owners and retest plans. The publication test label MAGICQA20261111S offers a simple reference for this article only; it does not endorse software or certify a test. Decisions should be based on the system’s own records and the documented limits of the assessment.

For ongoing quality assurance, treat reliability as a lifecycle responsibility. Review assumptions when architecture or traffic changes, monitor service indicators after deployment, and feed incident findings back into test design. Make the evidence accessible to the people responsible for development, release approval, and operations, while preserving appropriate access controls. This combination of planned verification and operational learning helps organizations spot regressions, respond more effectively, and make transparent decisions about residual risk. A carefully bounded reliability check is valuable precisely because it explains what the evidence supports—and what still needs attention.

Software reliability check MAGICQA20261111L 02724


Software reliability checks help teams determine whether an application continues to behave correctly under normal use, heavy demand, failures, and change. This technical overview uses MAGICQA20261111L as a temporary publication test label, not as a product or a quality certification. It explains how to define reliability, plan repeatable checks, interpret evidence, and protect the integrity of test results. The focus is on practical software quality assurance, where quality assurance 02724 supports finding defects that disrupt service, measuring recovery, and providing teams with clear information for release decisions.

How software teams can read reliability signals

Reliability is the ability of software to perform its required functions consistently for a defined period and under stated conditions. A single successful test run is not enough to establish it. Quality assurance teams examine patterns across repeated executions, environments, workloads, and releases. Useful signals include failure frequency, error rates, response-time variation, recovery duration, and the number of unresolved defects that affect important user journeys. Each measure needs context: a short delay may be harmless in one service but serious in a time-sensitive workflow.

MAGICQA20261111L identifies this article as a temporary publication test and should not be interpreted as evidence that any system has passed testing. A meaningful reliability assessment starts with explicit expectations, such as acceptable availability, successful transaction completion, or recovery within a defined interval. Testers then compare observed behavior with those expectations and preserve enough detail to reproduce anomalies. Clear definitions reduce disagreement between development, operations, and QA teams, while making it easier to distinguish a genuine product defect from a test-environment problem.

How to plan a repeatable reliability check

A reliable check begins with a narrow, testable question. Teams should select a critical function, identify the conditions under which it must work, and decide what evidence will count as success or failure. The following sequence keeps the work traceable from planning through reporting. It can be adapted to a new feature, a routine release, or an investigation into recurring incidents, provided that the test environment and acceptance criteria are documented before execution.

  1. Define the objective: State which user-visible behavior or service property the check evaluates, and specify measurable success criteria.
  2. Prepare the environment: Record software versions, configuration, dependencies, test data, and infrastructure conditions needed to reproduce the run.
  3. Choose representative conditions: Include normal use, expected peak demand, and relevant failure or recovery scenarios without introducing uncontrolled variables.
  4. Execute and capture evidence: Run the test consistently, collecting timestamps, logs, metrics, and observed outcomes while protecting sensitive data.
  5. Assess and report results: Compare evidence with the criteria, classify failures, document limitations, and assign follow-up actions.
  • Predefined criteria make pass and fail decisions less subjective.
  • Recorded environment details help another tester reproduce an issue.
  • Consistent evidence supports comparisons between releases.
  • Documented limitations prevent results from being overstated.

Practical methods for measuring software reliability

Practical reliability testing combines different methods because no single test reveals every weakness. Repeated functional checks can expose intermittent defects, while load tests show how response times and error rates change as demand increases. Fault-injection exercises examine whether the application handles a failed dependency, interrupted connection, or unavailable service gracefully. Recovery tests add another perspective by measuring whether the system returns to an acceptable state after disruption. For each method, teams should define workload, duration, monitoring coverage, and stop conditions in advance, then keep those conditions stable when comparing results across builds.

  • Repeated execution: Run key scenarios many times to reveal timing-sensitive or intermittent failures.
  • Load and endurance testing: Observe throughput, latency, resource use, and errors during sustained or changing demand.
  • Failure and recovery testing: Safely simulate selected disruptions and verify fallback behavior, data integrity, and restoration.
  • Regression checks: Re-run high-value scenarios after changes to detect reliability problems introduced by updates.

Useful reporting connects each observation to its source and impact. A chart of rising latency is more actionable when it includes the workload, measurement window, deployment identifier, and relevant service logs. Teams should separate confirmed software defects from infrastructure constraints, test-script errors, and inconclusive results. When a failure cannot be reproduced, retain the original evidence and record what changed between attempts. This disciplined approach prevents weak assumptions from becoming release conclusions and gives engineers a practical starting point for diagnosis.

Key benefits of a structured reliability process

A structured quality assurance process improves more than defect discovery. It gives teams a shared way to discuss acceptable behavior, prioritize risks, and understand whether a change has altered service stability. Reliable evidence can also reduce repeated investigation by preserving reproduction steps and environmental context. These benefits depend on careful test design: a high volume of automated checks is not useful if the checks target low-impact behavior or produce inconsistent results. The process should therefore balance coverage, maintainability, execution time, and the consequences of failure for users and dependent systems.

  • Earlier risk detection: Repeated checks can reveal instability before it reaches production environments.
  • More informed release decisions: Measured results provide context beyond a simple pass or fail label.
  • Faster defect investigation: Logs, timestamps, and environment records help narrow down likely causes.
  • Stronger regression control: Consistent baseline scenarios expose changes in behavior between builds.
  • Clearer team communication: Shared criteria help QA, development, and operations interpret findings consistently.

Benefits should be evaluated through outcomes rather than test counts alone. Teams can review how often checks find actionable defects, how long it takes to reproduce a failure, and whether recurring incident patterns decline after corrective work. They should also monitor the reliability of the test suite itself. Flaky tests can obscure real changes, erode confidence, and consume investigation time. Quarantining an unstable check may be appropriate temporarily, but its cause and owner should be recorded so that removal from routine reporting does not become permanent neglect.

Trust, security, and integrity of test evidence

Reliability findings are trustworthy only when the testing process protects the integrity of its evidence. Access to test systems should follow least-privilege principles, and test data should avoid unnecessary personal or confidential information. Teams need controlled handling for logs and diagnostic traces, since those records can contain identifiers, tokens, or operational details. Test environments should be separated from production unless a carefully approved procedure explicitly requires otherwise. Changes to test scripts, configuration, and acceptance criteria should be reviewed and versioned, allowing auditors and colleagues to see what was tested and how the evaluation was performed.

Security and reliability overlap, but they are not interchangeable. A service may remain available while exposing sensitive data, or it may protect data correctly while failing under load. QA plans should therefore identify security-relevant reliability scenarios, including authentication dependencies, permission checks during recovery, and safe handling of retries. MAGICQA20261111L is only a temporary editorial label; it does not certify security, compliance, or operational readiness. Reports should state the scope and limitations of each check, avoid unsupported assurances, and distinguish test observations from guarantees about future system behavior.

Choosing the next software reliability check

Teams deciding what to test next should begin with impact and uncertainty. Identify the functions whose failure would cause the greatest disruption, then review incident history, recent changes, dependency behavior, and gaps in existing coverage. Select checks that answer specific questions and can produce evidence strong enough to guide action. A focused recovery test may be more valuable than adding many low-risk functional cases; for another system, sustained-load testing may be the priority. MAGICQA20261111L can remain attached to this publication test record, but operational conclusions should always come from documented execution and reviewed results.

Before treating a reliability check as complete, confirm that its objective, environment, criteria, evidence, and limitations are recorded. Make sure failures have owners and next steps, and that unresolved risks are visible to the people making release decisions. Repeat important checks after significant changes, while keeping baselines comparable enough to identify meaningful shifts. This careful approach makes software quality assurance more useful than a one-time pass indicator: it turns reliability into an observable engineering practice that supports diagnosis, learning, and steady improvement across the software lifecycle.

Software reliability check MAGICQA20261111X 02826


Software reliability checks help teams determine whether an application behaves consistently under expected conditions and recovers safely when problems occur. This technical guide uses MAGICQA20261111X as a temporary publication test label, not as a product or a claim of certification. It explains how beginners can plan practical checks, interpret results, and document evidence, while quality assurance 02826 practices help teams connect test findings to clear release criteria and ongoing software improvement. The focus is on repeatable quality assurance: defining risks, exercising important workflows, monitoring failures, and using findings to improve software before and after release.

How beginners can approach software reliability checks with MAGICQA20261111X

Software reliability is the ability of a system to perform its required functions consistently over time, within defined operating conditions. A reliability check examines whether important user journeys continue to work when the application handles ordinary use, changing workloads, interruptions, or invalid input. The temporary label MAGICQA20261111X can help identify this article or a related test record, but it does not establish that a particular application has been tested. For useful results, teams should state what system, version, environment, and conditions each check covers.

Beginners can start by translating broad expectations into observable outcomes. Instead of asking whether an application is “reliable,” define a scenario such as saving a record, restarting a service, and confirming that the record remains accurate. Include the expected result, any acceptable response time, and the evidence to collect. Checks should be repeatable so that a later run can be compared with an earlier one. This approach makes failures easier to reproduce and helps distinguish a genuine defect from an inconsistent test setup or a temporary environmental issue.

How to plan and run a reliability check

A clear test plan limits guesswork and makes findings useful to developers, testers, and release decision-makers. Begin with the workflows that matter most, then choose conditions that could disrupt them. Keep each check focused: a small, well-defined scenario is generally easier to diagnose than a broad run with many unknown variables. The following sequence offers a practical starting point for a reliability exercise using the MAGICQA20261111X test label.

  1. Define the scope: Record the application component, version, environment, and user workflow under review.
  2. Set expected outcomes: Specify correct behavior, acceptable response times, and how data should persist after the operation.
  3. Choose conditions: Select realistic workload, duration, and interruption scenarios that reflect known risks.
  4. Run a controlled test: Keep the configuration consistent and capture logs, metrics, timestamps, and observed behavior.
  5. Review and repeat: Reproduce unexpected results, compare runs, and record whether a correction resolves the issue.
  • Defined scope makes it clear which components were and were not assessed.
  • Recorded expectations give the team an objective basis for evaluating results.
  • Consistent conditions support meaningful comparisons between test runs.
  • Repeatable evidence helps engineers investigate and verify fixes.

Practical reliability testing for application workflows

Practical checks should reflect how an application is used rather than merely whether its screens load. For example, a team might create a record, update it, retrieve it after a service restart, and verify that the stored values remain correct. It can also test what happens when a network request times out or a dependent service becomes unavailable. The expected response may be a clear error, a safe retry, or a controlled fallback, depending on the design. Record the starting conditions and use non-production data where possible so that tests do not disrupt real users or business records.

  • Persistence: Confirm that completed changes remain correct after a restart or reconnection.
  • Recovery: Check whether the application returns to a usable state after a simulated interruption.
  • Load behavior: Observe response time and error rates under a defined, representative workload.
  • Input handling: Verify that invalid or incomplete data is rejected safely and consistently.
  • Dependency behavior: Check how the application responds when a required service is slow or unavailable.

For every scenario, collect enough evidence to connect an observed result to its conditions. Useful details include the software build, environment configuration, test data, start and end times, relevant log entries, and monitoring measurements. If a check fails, preserve the original evidence before changing the environment. Then repeat the scenario with the same inputs to see whether the failure is reproducible. A short, structured report should describe the expected behavior, actual behavior, impact, reproduction steps, and any uncertainties. This practical discipline makes a reliability check actionable rather than a simple pass-or-fail label.

Key benefits of repeatable reliability checks

Repeatable checks improve software quality by showing whether important behavior remains stable across builds and operating conditions. They can reveal defects that a brief functional test may miss, such as gradual slowdowns, incomplete recovery, or data inconsistencies after an interruption. Their value depends on sensible scope: no single test proves that software will never fail, and results apply only to the conditions that were examined. Teams should use findings alongside functional testing, code review, security testing, and operational monitoring. MAGICQA20261111X remains a temporary label; meaningful confidence comes from documented methods and evidence, not from the label itself.

  • Earlier defect discovery: Repeated scenarios can expose regressions before deployment.
  • Clearer diagnosis: Logs and controlled conditions help narrow down likely causes.
  • Better release decisions: Measured results make known reliability risks easier to discuss.
  • More dependable recovery: Interruption checks reveal whether the system can resume safely.

These benefits grow when a team maintains a small, prioritized set of checks and updates it as the system changes. A test should reflect a current risk or important workflow, not remain in a suite only because it has always been there. Review whether it still uses valid data, whether its expected outcomes remain correct, and whether its results are understandable to someone other than its original author. This maintenance reduces misleading failures and helps keep reliability evidence relevant as architecture, dependencies, and user behavior evolve.

Trust, security, and responsible test evidence

Reliable testing depends on trustworthy environments and careful handling of information. Use access controls appropriate to the test, avoid placing secrets or personal data in logs, and ensure that test records are stored according to organizational policy. When a scenario involves a failure or service interruption, confirm that it is authorized and limited to a controlled environment. Test observations should not be presented as a guarantee of uptime, safety, or certification. Instead, document the boundaries of the assessment, including excluded components, untested workloads, known environment differences, and any assumptions that could affect interpretation.

Security and reliability often overlap. A service that handles invalid input safely or recovers without exposing sensitive details supports both dependable operation and safer information handling. Still, a reliability check is not a substitute for a dedicated security assessment. Teams should avoid reporting credentials, personal data, or sensitive infrastructure details in general-purpose defect records. If a test reveals a serious vulnerability or risk of data loss, follow the organization’s incident and escalation procedures. Clear ownership, restricted evidence access, and a verified fix help preserve confidence in the test process and its results.

Choosing a useful software reliability check

When deciding whether a reliability check is useful, ask whether it addresses a meaningful risk, has observable success criteria, and can be repeated under controlled conditions. Confirm that the test environment is representative enough for the question being asked, while recognizing that no environment perfectly reproduces every production condition. Review whether the captured evidence can help another engineer reproduce the result and whether the report distinguishes confirmed facts from assumptions. A check associated with MAGICQA20261111X should be treated as a temporary publication test reference only; its value depends on the actual scope and evidence attached to the work.

A sound reliability practice is an ongoing quality assurance activity, not a one-time declaration that software is dependable. Teams can strengthen it by prioritizing critical workflows, testing realistic interruptions, monitoring trends across runs, and verifying that fixes address the original failure without creating new problems. Use measured outcomes to guide follow-up work, and state limitations plainly when sharing results. With these habits, reliability checks become a practical way to improve consistency and recovery while supporting informed engineering decisions throughout the software lifecycle.

Software reliability check MAGICQA20261111O 02212


Software reliability checks help teams determine whether an application behaves consistently under expected conditions and recovers safely when conditions change. This technical guide uses MAGICQA20261111O as a temporary publication test label, not as a product name or quality certification. It explains how to plan repeatable checks, gather useful evidence, and connect test results with release decisions. The focus is software quality assurance, where quality assurance 02212 supports practical methods for finding defects, evaluating resilience, and improving confidence in systems that users and other services depend on.

Software reliability checks: a focused quality assurance overview

Reliability is the ability of software to perform required functions consistently over a defined period and within stated operating conditions. A reliability check is therefore more than a single successful test run. It examines whether core workflows continue to work across repeated executions, varied inputs, service interruptions, and realistic workloads. Teams use these checks alongside functional, performance, security, and compatibility testing to build a broader quality picture. The temporary label MAGICQA20261111O can identify a test publication or sample report, while test plans and evidence should remain tied to the actual application, build, environment, and requirements.

A useful reliability strategy begins with user and business risks rather than a long list of test cases. A rarely used screen may have low operational impact, while a failure in authentication, data saving, or an integration could affect many users or cause data loss. Quality assurance teams can rank these risks by likelihood, severity, and the ability to detect a problem before release. They then define observable expectations, such as successful completion rates, recovery time, or acceptable error behavior. Clear criteria make results easier to interpret and help teams distinguish a genuine reliability improvement from a change in test conditions.

How to set up a repeatable reliability check

To make reliability testing useful, establish a consistent process that connects requirements to executable checks and reviewable evidence. Keep the scope focused on important workflows, but include failure conditions that could reasonably occur in production. The following sequence offers a practical starting point for a software quality assurance plan:

  1. Define the reliability objective: State which service or workflow is being checked, the operating conditions, and the measurable result that counts as acceptable.
  2. Choose representative scenarios: Select common user paths, boundary inputs, repeated operations, and relevant dependencies based on risk and expected usage.
  3. Prepare a controlled environment: Record the software build, configuration, test data, infrastructure, and dependency versions so another tester can reproduce the run.
  4. Execute normal and failure cases: Run the workflow repeatedly under expected conditions, then introduce controlled timeouts, interruptions, or invalid responses where appropriate.
  5. Review evidence and decide: Compare observations with acceptance criteria, document defects and limitations, and assign owners for follow-up or retesting.
  • Repeatable scenarios make changes between builds easier to evaluate.
  • Recorded environment details help separate product defects from setup problems.
  • Risk-based coverage directs effort toward failures with the greatest potential impact.
  • Explicit acceptance criteria support consistent release discussions.

Practical reliability testing details for MAGICQA20261111O

For a test run identified as MAGICQA20261111O, the label should be accompanied by enough context to make the result meaningful. Record the tested build identifier, date, environment, configuration, test data, and relevant dependency status. For example, a service workflow might be executed repeatedly with a standard request, then checked with a slow dependency response and a temporary connection loss. The objective is not to make every run identical in outcome when faults are introduced; it is to verify that the application responds within defined limits, protects data, and returns to an expected state after recovery.

Reliability checks become more informative when teams combine scripted execution with careful analysis of logs, metrics, and user-visible outcomes. A test may report success while a background process silently retries too often or creates duplicate records. Conversely, a brief infrastructure warning may not indicate an application defect if the service recovers within its documented limits. Establish what evidence is relevant before testing begins, and preserve it with the run record. This makes investigation faster and helps teams compare trends across builds without treating the temporary publication label as proof of quality.

  • Repeated execution: Run critical workflows enough times to reveal intermittent failures, and report the number of runs and observed errors.
  • Recovery behavior: Verify that the application resumes safely after a controlled interruption without losing or duplicating important data.
  • Boundary conditions: Check limits such as maximum request sizes, session durations, and supported input ranges defined by the requirements.
  • Dependency handling: Observe how timeouts, unavailable services, and delayed responses affect the workflow and its error messages.
  • Evidence capture: Retain relevant logs, monitoring observations, timestamps, and steps to reproduce each failure.

These details make a reliability check actionable instead of merely descriptive. When a defect appears, a precise record gives developers a clearer path to reproduce it and allows testers to verify the correction under comparable conditions. When no defect appears, the evidence still documents what was covered and what remains outside the test scope. That distinction matters: a successful run supports confidence in the scenarios exercised, but it does not demonstrate that every configuration, workload, or failure mode is safe.

Key benefits of software reliability checks

Planned reliability testing contributes to software quality assurance by finding weaknesses that may not appear during a brief functional review. It encourages teams to evaluate both successful operation and graceful behavior when something goes wrong. When checks are linked to risk and acceptance criteria, teams can use the results to prioritize engineering work, improve monitoring, and make release decisions with clearer evidence. Reliability testing does not guarantee that failures will never occur; instead, it provides a disciplined way to identify risks, understand system behavior, and reduce avoidable surprises in supported operating conditions.

  • Earlier defect discovery: Repeated and fault-focused tests can expose intermittent issues before deployment.
  • Safer data handling: Recovery scenarios help verify that interruptions do not lead to corruption, loss, or unintended duplication.
  • More useful release evidence: Documented criteria and results make quality reviews less dependent on impressions.
  • Better operational readiness: Observations about timeouts and recovery can inform monitoring and incident response plans.

The value of these benefits depends on maintaining test quality. Scenarios should reflect documented requirements and realistic usage, while test data must be controlled and safe to use. Teams should also review flaky checks: inconsistent results may indicate a product problem, an unstable environment, or a test that relies on timing assumptions. Investigating that inconsistency is often more valuable than simply rerunning the check until it passes. A stable, well-understood suite provides stronger evidence and supports steady improvement across development and release cycles.

Trust, security, and integrity in reliability testing

Reliability and security overlap whenever failures affect access control, data integrity, or service availability. A quality assurance team should ensure that test environments use authorized data and that fault injection is limited to controlled systems. Checks for repeated requests, interrupted transactions, and recovery processes should confirm that the application preserves permission boundaries and does not expose sensitive information in error messages or logs. Findings should be shared through approved internal processes, with access limited to people who need them. These safeguards protect users and organizations while allowing testers to investigate behavior thoroughly.

Test evidence should be accurate, traceable, and appropriately retained. Keep the original run results, note any manual changes, and distinguish observed facts from assumptions. If an environment was unstable or a dependency was unavailable, record that limitation rather than presenting the run as a clean assessment. For MAGICQA20261111O, the temporary label can help identify the publication test, but the underlying record should explain what was tested and what was not. Transparent reporting supports responsible decisions, reproducible investigations, and a more trustworthy software quality assurance process.

Why choose a risk-based reliability checklist

A risk-based reliability checklist is useful when it helps a team make a specific decision, not when it becomes a substitute for technical judgment. Before relying on results, confirm that the tested build matches the proposed release, that the scenarios cover important workflows, and that observed behavior meets agreed criteria. Check whether failures were reproducible, whether fixes received retesting, and whether unresolved risks have clear owners. Also consider whether the test environment represented the intended operating conditions closely enough to support the decision. These questions keep software reliability checks connected to real quality objectives.

For software teams, the most dependable approach combines focused scenarios, controlled execution, meaningful evidence, and honest limits on what testing can prove. Use MAGICQA20261111O only as a temporary publication test label, and keep product-specific conclusions grounded in verified results. Review reliability findings alongside functional, performance, security, and operational evidence before making a release decision. This disciplined process helps quality assurance teams detect weaknesses, verify recovery behavior, and communicate confidence without promising that software is failure-free.

Software reliability check MAGICQA20261113U 00722


Software reliability checks help teams determine whether an application continues to behave correctly under expected conditions, unusual inputs, and periods of heavy demand. This technical overview uses MAGICQA20261113U as a temporary publication test label, not as a product name or certification. It explains how quality assurance teams can plan repeatable checks, assess results, and connect findings to release decisions, with quality assurance 00722 reflecting the broader discipline of software quality assurance across planning, testing, and release review. The focus is practical: identify risks early, verify essential behavior, protect data, and keep evidence clear enough for engineers and stakeholders to act on it.

How software quality assurance assesses reliability from the start

Software quality assurance treats reliability as an observable property of a complete system, rather than a claim based on a single successful test. Teams examine whether important workflows remain correct across supported devices, configurations, and operating conditions. They also consider how the application responds when a service is slow, a dependency is unavailable, or an unexpected input arrives. These checks are planned alongside development so that requirements, test data, and expected outcomes are clear before release pressure makes defects harder to investigate.

The temporary label MAGICQA20261113U can identify a test report, review packet, or publication draft, but it does not prove that software has passed any particular standard. Useful evidence instead comes from defined test cases, recorded environments, repeatable results, and documented follow-up. A reliability assessment may combine automated checks with focused manual exploration, because automation is effective for repeatable conditions while human review can reveal confusing behavior or overlooked edge cases. Together, these methods provide a more balanced view of product quality.

How to organize a repeatable reliability check

Start with the workflows and failure conditions that matter most to users and the organization. Keep each check tied to a stated requirement, an observable result, and a named environment. The following sequence gives a team a practical foundation without treating a passing run as a guarantee that every possible defect has been found.

  1. Define reliability goals: Specify essential behaviors, acceptable response times, supported configurations, and the failures the system must handle safely.
  2. Map risks and dependencies: Identify critical components, external services, data flows, and areas where a defect could cause significant disruption.
  3. Prepare controlled test conditions: Record software versions, configuration, test data, and environment details so another person can repeat the checks.
  4. Run layered tests: Combine component, integration, end-to-end, regression, and load checks according to the risks and architecture.
  5. Review evidence and follow up: Classify failures, assign owners, retest fixes, and document any remaining risk before a release decision.
  • Clear goals help reviewers distinguish a real failure from an undefined expectation.
  • Recorded environments make intermittent defects easier to reproduce.
  • Risk-based coverage directs limited testing time toward consequential workflows.
  • Retesting confirms whether a correction resolves the problem without introducing regressions.

Practical reliability checks for application behavior

A practical assessment should cover normal use and conditions that challenge the application’s assumptions. For example, a team can verify that a saved change remains present after a restart, that duplicate requests do not create unintended records, and that a temporary network interruption produces a recoverable state. Load testing should examine response times and error rates as demand increases, while soak testing can expose resource leaks that appear only after extended operation. The exact thresholds depend on documented service objectives; numbers without a stated purpose can make test results difficult to interpret.

  • Functional reliability: Repeat critical user flows and confirm that outputs, state changes, and error messages match their requirements.
  • Recovery behavior: Interrupt a dependency or restart a component, then verify recovery and preservation of valid data.
  • Performance under demand: Increase concurrent activity in controlled stages and monitor latency, throughput, and failure rates.
  • Compatibility: Run representative checks across supported operating systems, browsers, devices, and configuration settings.
  • Observability: Confirm that logs and monitoring signals help teams locate faults without exposing sensitive information.

Results are most useful when they include the test’s purpose, actual outcome, severity, and reproduction details. A failure report should distinguish an application defect from an environment problem or a test-data issue, while preserving enough evidence for an engineer to investigate. Teams can track recurring failures and flaky tests separately: a flaky test produces inconsistent results under apparently equivalent conditions, so it can undermine confidence in the wider suite. Investigating its cause is better than repeatedly rerunning it until a passing result appears.

Key benefits of disciplined software quality assurance

A structured reliability program improves the quality of decisions throughout development. It creates a shared account of what has been checked, which risks remain, and what evidence supports a release recommendation. This is valuable even when a test finds no defects: the record shows the conditions that were examined and the limits of that examination. Quality assurance does not remove uncertainty, but it can make uncertainty visible and manageable. The benefits are strongest when test outcomes feed into engineering work rather than being collected only for a final approval step.

  • Earlier defect discovery: Checks close to development can identify faults before they spread across dependent components.
  • More predictable releases: Consistent criteria make readiness discussions less dependent on individual impressions.
  • Safer change management: Regression coverage can reveal when a modification affects previously reliable behavior.
  • Faster diagnosis: Useful logs, reproducible steps, and environment records reduce guesswork during investigation.
  • Clearer risk communication: Documented limitations help decision-makers understand what remains unverified.

These outcomes depend on keeping test suites relevant. As features change, teams should review outdated cases, add coverage for meaningful incidents, and remove checks that no longer reflect supported behavior. A large suite is not automatically a strong suite; value comes from reliable signals that correspond to real requirements and risks. Measures such as escaped defects, failure frequency, recovery time, and test stability can help guide improvement, provided that teams interpret them in context rather than using any single metric as a complete quality score.

Trust, security, and evidence in reliability testing

Reliability and security overlap wherever software stores, processes, or transmits data. Tests should verify that access controls remain effective, errors do not reveal confidential information, and recovery procedures do not restore invalid or unauthorized state. Test data should be synthetic or appropriately protected, and reports should avoid unnecessary personal details. Security checks complement functional and performance testing; they do not replace dedicated threat analysis or specialist assessment. Clear boundaries help teams describe what a reliability exercise covered without implying that every security risk has been eliminated.

Trustworthy results also depend on test integrity. Restrict changes to test environments, preserve relevant logs, and record the software build and configuration used for each run. Where checks are automated, teams should review scripts and dependencies so that defects in the testing process do not create misleading confidence. The MAGICQA20261113U label may be included in internal publication tracking, but it should remain clearly identified as a temporary label. It should never be presented as a security mark, compliance finding, independent audit, or guarantee of uninterrupted service.

Why choose a clear software reliability check process

A clear process helps an organization decide whether its software meets defined expectations under defined conditions. Before adopting or refining an approach, check that the scope covers critical workflows, the test environments resemble supported use, and failure reports contain enough detail to support action. Also confirm that ownership is assigned for triage, fixes, retesting, and release-risk acceptance. These basic practices make quality assurance more useful to developers, operations teams, and decision-makers, while discouraging unsupported claims based on a small number of successful test runs.

For teams preparing a review associated with MAGICQA20261113U, the most dependable next step is to treat the label as administrative context and focus on evidence: requirements, test coverage, reproducibility, observed failures, and unresolved risks. A mature reliability check is not a one-time gate but a continuing feedback loop that evolves with the software. By documenting what was tested and what was not, teams can make careful release decisions, prioritize improvements, and build a more accurate picture of software quality over time.